sábado, 4 de julio de 2015

Talk like Hawking: Teaching with a synthetic voice

Hiya! I have been pretty busy and also a bit disappointed in life lately (soo dramatic!), but blogging has always been good medicine, so I'm back! 


***
I have always found voice matters interesting, and I do pay a lot of attention to people's voices in general. They have the power of generating feelings, immediate gut feelings, in me. 

For many years, I was concerned about my own voice, as it would invariably become hoarse and then turn to a whisper at least twice or three times a year. I was teaching over 55 periods a week and as we all know, our teaching activity is a 100% dependent on our voice (there's a limit to emergency video sessions one can plan when your voice's "on the blink"!). So I was basically "killing my voice softly".

Things changed for the better when I started training in vocal technique, and I will always be grateful to Carlos and Liliana at Instituto de la Voz for having saved me from potential hiatus and nodule problems. And I have now got the huge responsibility of passing on these techniques and voice care tips to my teacher trainees, which I try to do on a regular basis. 

Now. This whole babble is related to today's blog post, since in spite of all my care, my voice was gone yesterday due to an irritating bout of flu or something (and the winter temperatures hitting our country like we haven't seen for a number of years!). With several classes a day to teach, all pronunciation-related, how do you keep going?

Well, the obvious answer is: "You don't. You go home, you see a doctor, you get some rest for a few days till you recover". And that would be the right answer. But it's not always possible. So here's what I did yesterday.

***

Teaching Phonetics the Hawking-style

We are all familiar with Stephen Hawking. We all know what a miracle it is that he can share all his wisdom and knowledge with us through a computer. Therefore, I used him as an inspiration to try to teach my class without having to strain my voice.


So here's what I have done:

1) I typed part of my lecture at home, on my tablet (It runs an Android Kit Kat operating system).

2) I downloaded the following app: Talk, and selected English (GB) as the output voice. (I was in a bit of a hurry, so this is the first app that worked for me, but I will be comparing it with others below)

3) I tried the app out, and noticed that to make it less "robotic", I had to "teach" the system to read the way I wanted it to read. That is, I had to input extra punctuation marks, such as "" and ; to allow the machine to chunk units apart or produce some basic intonation patterns which would allow my audience to follow more clearly.  I also had to simplify my clauses and exploit thematic marking on the text to make sure my synthetic voice would signpost topics and paratones more clearly to my students.

4) I gave my tablet Internet access via my phone, using it as a router, since this app needs a working connection, and of course, I connected my tablet to my portable speakers.

The immediate result? Giggles, of course! It was fun. I got called "Marina Hawking". But it was, of course, not the same as being able to respond to students' queries in real time. I eventually had to replace the use of my tablet for the whiteboard when I needed to reply to students' queries on the spot. 

I wanted to brag and I finished my lesson by typing in "That's all, folks!", but the awful rendering by the system (giving "folks" a separate IP and using a fall) spoiled all the fun! (Try it!)


However, I was teaching a theoretical class, so the app did the trick. I had a Lab lesson right afterwards, and it was really difficult to succeed in this way. I was not in a position to deliver feedback on the spot, since obviously, my app would not read IPA symbols, and the need for synchronous comments while the student is reading out, or speaking, does not match my typing speed. In this particular case, gestures and the whiteboard did the job. Sort of. My teacher assistant allowed the class to happen, to be honest!

(Had I had a data projector, I would have projected the text my students were reading, and I would have highlighted their slips and mistakes on the spot, to allow them to at least see what I was trying to comment on! I could have also projected some vids and audio files from some of the pronunciation apps I reviewed in the past.)

So all in all, a text-to-speech act may save the day, but you defo need to take care of yourself and try to get your voice back asap!

***
Free Text-to-Speech Apps

After yesterday's experience and while resting in bed, I decided to review a few other apps that may do the job nicely.

(I will review them together, as they are very similar and use the same voice database. The same text was read by both apps identically, and with the same voice. They only differ in their interface.)
  • These apps allow you to paste your text, or type it straightaway, and play it out. (Easy Text to Speech does not require any text-pasting, it just reads from your clipboard)
  • You are able to choose from a long list of languages and accents.
  • You can export or save your audio file.
  • You need an active data or Internet connection.
  • Tip! You need to "overpunctuate" your text to avoid a robotic output.


This application uses its own voice database. You choose an accent, and a speaker, and you download the voice database for that voice in particular. I have chosen "Amy, UK English". So far, it sounds like the most natural reading option, because the voice is somehow soothing. 

It has not, of course, reached the state of artificial intelligence, in that it does not chunk my text the way I would like it to, and it does not always employ the intonation I expect, but it does recognise a few chunks and it appears to be able to recognise patterns of declination and paratones. 

This application also allows you to set your preferred pitch and speech rate for the chosen voice.

From what I have been able to make out, it does not need an active Internet connection. The voice data files I have downloaded were 150 MB, so I guess it should all be "there".

Even though it is not a text-to-speech app but rather a translator, I cannot help feeling surprised about the changes that Google has introduced to their voices and to the whole reading aloud experience. It still sounds pretty "robotic", but there are some chunks of language that the system automatically recognises and reads out with some fixed intonation patterns. This creates an overall "weird" effect, since you hear upsteps, downsteps and sudden tone changes that make the whole text sound incohesive at times, but less so, if compared to what it was like last year!

BTW! I have found a tip on how to get Google to read out a phrase out for you. Type in this address in your browser:

http://translate.google.com/translate_tts?tl=en&q=type your phrase here

And replace the bit that says "type your phrase here" with your own phrase, and voilá!


Much as I love Google, Microsoft has done a better job in terms of making their performance of read-out texts more natural. The Bing Translator option presents, in my humble opinion, a better chunking, and more natural selection of intonation patterns. 

See for yourself! Compare the output versions of a short paragraph of my lesson by both Google Translate and Bing Translator. Look out for some interesting word stress choices as well!


***

Final remarks and a few extras...

  • A full selection of Android text-to-speech apps is available here.
  • For a list of other possible uses for text-to-speech for language learning, and ideas to aid students with special needs, you can check out these resources:


Hope this blog post has been of use! It has certainly inspired me to start considering writing a paper on synthetic-speech talk and intonation!

martes, 19 de mayo de 2015

Podcast-y post #2: Your accent, your Patronus - Yet another reflection in passing

Some time ago, I recorded my first podcast on accents and the"Voldemort effect". Here's another post/ramble, unedited, heart-to-mind, mind-to-heart talk, of this complex feature of attaining, sustaining, and more importantly, owning and loving your accent.

It was inspired by my teacher trainees in their last year, and the challenges I find while teaching these advanced students.

Usual pre - listening warnings (I am a teacher, after all, and I am my own teacher, as well):
☂I have mispronounced "Patronus". I should have probably pronounced it: /pə'trəʊnəs/. ☂Plus, there are a few choices in word stress, nucleus placement, tone and tonality which I would have made differently. ☂A few " dysfluencies" as well, sorry to say!

As usual, many of these posts emerge as "reflections in passing", almost through a "stream of consciousness" technique, and editing this post would have meant spoiling the spontaneity of this moment of realisation, and thought.

So here it goes. Hope you will enjoy it.


lunes, 11 de mayo de 2015

Pronunciation, Phonesthesia and Realia: The case of the STRUT vowel (Part 2)

In my latest post, I compared General British STRUT and its variants to Riverplate Spanish /a/. I reviewed some articulatory and also acoustic features, and I also went over some basic notions of Speech Perception theories. I established that many of my Riverplate Spanish learners may associate English /ʌ/ with their Spanish /a/ "magnets" and may, thus, find the differentiation between both vowels challenging, both for perception and production.

(BTW, apparently, the differentiation between English /ʌ/ and other vowels appears to be quite an issue for many speakers of English as an L1 or L2, as Ettien Coffi (2014) reveals in this paper from the Proceedings of the 5th Pronunciation in Second Language Learning and Teaching Conference - page 11 onwards)

In this post, I would like to present some of the tips & tricks I have collected over the years (and I will try to acknowledge my colleagues' contributions whenever I can!). My claim will be that many "tips" do the job when they help create an image of the L2 sound which may help the learner steer away from their L1 quality, and that this may not necessarily just be reliant on making the right articulatory movements.

This is why some of my suggestions will draw on creating "mental images" through the contributions of Phonesthesia, and Realia; images which should appeal not only to visual aspects, but also auditory, and emotional resources.
***
A few definitions first:

Realia refers to the introduction of real-life objects in the classroom, to make the learning experience of certain concepts and routines more vivid. This technique also enables students to engage all their senses and learning styles. We can introduce actual objects, or we can create virtual situations that may allow students to experience similar emotions and actions as those recreated in the real situations.
(You can get some teaching ideas on using teaching aids in the TEFLSurvival blog, and the BusyTeacher website.)


Phonesthesia refers to the analysis of "sound symbolism". It basically studies how clusters of sounds may center around lexical sets that express similar meanings. So for example, in the Dictionary of Sound by Margaret Magnus, you can find a number of STRUT words that could be related to "puffy things":  plush, fuzz, fluff, cuff, muff, ruff.

This reminds me of a poem by Tony Mitton, called "Fluff"

What's this here?
A piece of fluff.
I don't know where I get this stuff.
I'll blow it away
with just one puff.
Huff!
There. That's enough.

So the combination of vowel /ʌ/ and the /f/ quality, reminiscent of blowing, creates this "puffy" effect of fluff and makes the poem lovely for oral performance, and effective! 

***
As a College student, I had a hard time fine-tuning my STRUT away from my Spanish /a/. I was given instructions, I  knew I had to drop my jaw, but still, it sounded pretty much like my own Spanish /a/. (Mind you, my friend and colleague Prof. Francisco Zabala has found that the STRUT quality as an allophone is present in many Spanish combinations of "a" + sound /x/, as in "caja".)  And I see my students at Teacher Training College producing a similar type of Spanish /a/ sound. So after a few tries, after watching native speakers of English produce their STRUT sounds, analysing the way this jaw-dropping takes place for this sound, I came up with the first articulatory tip that worked for some of my students:

"Keep to the railings of the mouth". I asked my students to imagine that each of the two sides of their lips, or the corner of their mouths, had a vertical railing, and that there should not be any smiling, as it would defy the railings of the mouth, and that the articulatory movement should be downwards, not sidewards. I could not help thinking of these special types of puppets ventriloquists use:

Celebrity puppet
Image credit: David Noah. Flickr:https://www.flickr.com/photos/davidnoah/5170268541/

With this idea in mind, in one of my lessons, students were asked to place their fingers in the corners of their mouths in the puppet-like manner above, and look at themselves in a mirror/front facing camera of their mobile phones while producing STRUT words, trying to avoid a smile (which was tough, as they were having fun!).Therefore, this sound became the "puppet" sound (and for older Argentinians, this was the "Chirolita" sound, after a well-known ventriloquist in Argentina).
This articulatory tip did the trick for many students, but yet, not all of them really got to acquire a close quality; many students still produced a much fronter, or sometimes, opener vowel.

So I resorted to phonesthesia, and I thought of a few words I associated with the STRUT quality. By repeating the STRUT vowel to myself in isolation, I came up with these words (and a few others, after trying the marvellous Sound Search tool in the Cambridge Pronouncing Dictionary CD-Rom!)

  • Things falling and making noise: thud, plunge  
  • Unpredictable, shocking: abrupt, blunt, rough
  • Pushing, stabbing(?): thrust, chuck, cut, nudge, punch, butt

(BTW (deviation alert!), as a Miranda Hart fan, I could help laughing at myself while repeating these words!)

So with some groups of students, I tried playing around with the words above, getting into the mood of things "falling" or happening "abruptely", which acts in much the same way the downward movement of the jaws does, like a small "bite", even.

Encouraged by the success of this tip for some students, I started thinking about the realia of "emotions", the "tone" that this sound evoked in me, and I could not help feeling "dull", "disgusted" or "miserable", as with these words:
  • love
  • money
  • you suck!
  • duh!
  • yuck!
  • f*#k
And I said to myself (and forgive the vulgarity of it all!), "what makes you suffer? Love, or money?". So I asked my students to think about their most "miserable" feeling, place themselves in that "sad place" (a bit like many actors do), "pull a miserable face" and go for /ʌ/ . 

Credits: http://i3.mirror.co.uk/incoming/article4311979.ece/ALTERNATES/s615b/Kim-Kardashian-and-Kanye-West-arrive-for-a-dinner-at-Hakkasan.jpg
(I have a confession to make: I sometimes ask my students to produce the f-word. It works! Perfect STRUT qualities EVERY time!)

When using this strategy a few years ago, a student came up with the memory of losing a match as a kid, and remembering his father's disappointed reaction (a very sad place to go to, if you ask me!). So we worked on that emotion, and we created a situation in which a very stern father or mother would push their son or daughter to win a race. And I came up with this terrible (!) poem/song, with a "run, run, run" chorus to the melody of Pink Floyd's "Run like Hell". It does sound like a bitter and very dark poem, but as a dramatic technique, it did the trick!

In one of the lessons where I tried the poem, students worked in two teams, with one group acting as an audience, singing the "run, run" Pink Floyd chorus, and a second group "mumbling" the words of the poem as they all pictured the race and their son running. The "little play" that resulted of this poem reminded me of Hermione in the audience uttering the Confundus charm and Harry saying "Come on, Ron" in a sort of low murmur (Deviation alert #2!):


***
Somehow this idea of a "miserable" STRUT sound has been the most effective tip to help my students provide a version of /ʌ/ that drove them closer to a quality different from their Spanish /a/, and also from the "Happy, cheerful, /æ/" and the "Relaxed, cute, awwww-like, /ɑ:/":

***
As with everything, you can find your own way of adapting these tricks for your own lessons, taking into consideration the "classroom management" factor, because let's face it, pronunciation work may create a bit of a mess in the classroom!

And of course, as Adrian Underhill claims, multisensory pronunciation learning is the key. Building one's own proprioception, and supplementing this with mental, auditory and emotional images should, in some way or other, contribute to the uniqueness of our learners' styles and processes. As I always say, what may work for one student may not necessarily work for the other! (Another piece of evidence for the "messy" nature of pronunciation work, sorry to say!)

***

Final thought: It is funny that many of the nice things of life may also take STRUT, and they don't seem to "fit" with with sound. What shall we do about 
love, fun, feeling chuffed, abundance, bubbles ...and maybe, money?
I leave that to you!


viernes, 1 de mayo de 2015

Pronunciation, Phonesthesia and Realia: The case of the STRUT vowel (part 1)

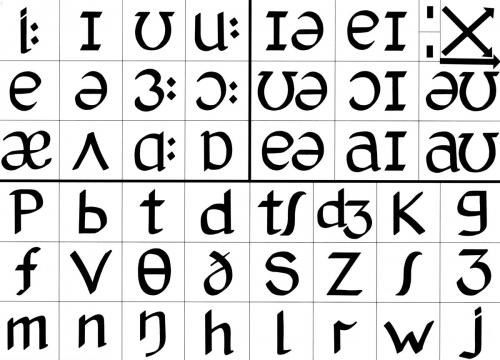
With the release of Adrian Underhill videos, I can now re-live some of the presentations of the IPA that my Phonetics tutor and trainer, Prof. Graciela Moyano, introduced when I was a first year student at College. It's just brilliant to go back to those moments of discovery of how our articulatory system works.
Adrian Underhill's phonemic chart. (I would probably do away with the centring diphthongs as they stand, using /ɛ:/ for /eə/ and maybe still keep /ɪə/)

I have completely embraced Adrian's belief and knowledge that "pronunciation is physical", and this motor side of pronunciation and our awareness of articulation through the different "buttons", as he calls them, is essential. However, out of his presentations, my independent reading, and my own teaching style, I have found that part of the process of acquisition of L2 features also lies on the images that we make of what the L2 features sound like.

Over the years, I have discovered that part of the fine-tuning processes we need to carry out to learn the sounds of L2 also involve affective aspects, including our own affective memory, and feelings. I have experienced situations in which students appear to be making the right articulatory movements, and still, there is something in the quality of the sound that does not "sound right". And in those cases, what I noticed is that it is the recourse to mental and affective images related to the sounds that appear to do the trick, rather than just the right lip or jaw position.

So in this post (which is, obviously, not a report on experimental research, so don't expect it to be so!), I will be going over a few techniques that I have used to include phonesthesia and realia in my pronunciation teaching. My focus this time will be on the STRUT vowel, /ʌ/, one which gave me a lot of trouble as a learner!

I will be covering a few different theoretical and practical areas on this post, which is why it will be divided into two:

Part 1: 
  • Speech Perception theories: a review with links to further reading materials.
  • English vowel STRUT /ʌ/and Spanish vowel /a/: a review.
Part 2:
  • Tips and tricks to teach STRUT
    • Articulation
    • Realia
    • Phonesthesia

***

Images, Categories, and Speech Perception Theories

When writing my research paper for my specialisation course in Phonetics I in 2006, I came across a huge number of acquisition and psycholinguistic theories which really helped me to make sense of and inform my teaching practices. Even though I am not an expert in acoustic or perceptual matters, I believe that some basic knowledge of theories of Speech Perception can actually aid our comprehension of what happens to our learners when faced with L2 pronunciation challenges.

Speech Perception Theories state that perception is categorical and not continuous (Liberman, 1985), that is, we perceive categories, no matter whether there is individual variation, and thus, we group sounds according to our perception. We can, in other words, say if a certain set of sounds are the same, or if they are different, despite the realisational differences of those sounds. The Perceptual Magnet Effect theory by Kuhl (1991) addresses similar issues for vowel sounds, by exploring in more detail how we can perceive the space or distance between the different variants we hear, to somehow establish what degrees of variation can be significant for us to associate a certain sound or stimulus to either another category, or to a "bad" (so to speak!) version of the category under scrutiny. This all appears to work pretty well for our L1, though there are a few "traps", as the McGurk effect reveals, when the information that the different senses provide do not appear to match:

If anything, the McGurk effect proves that we draw information from different multimodal sources, which is a very useful thing to know for those of us who train in L2 perception and production!

Now, when it comes to perception of L2 sounds, the "same-different" categorisation may fail, as we tend to interpret our L2 sounds from our own L1 targets, as Flege's Speech Learning Model (1995) states. So if we consider Kuhl's and Flege's models, we can predict that certain L2 qualities, if close to certain L1 targets, will be perceived as similar, and thus, learners may take longer to acquire them and create new categories for them.

Our learners, then, may create a mental image of what a particular L2 segment sounds like in the light of their already-existing images of the sounds in their L1. This means that in order to improve perception and production, we need to create new images and categories that will establish a perceptual distance between L1 and L2 sounds.

So in this post, I would like to explore the fact that one of the ways in which we can displace the L1 images in favour of L2 categories is by creating images that may exceed the information that the visual and tactile senses can give us for the articulation of the sound, and even the auditory information we can initially get. I would like to propose ways in which affective and visual memories can activate these new sounds in the shape of perceptual images.

***
The STRUT /ʌ/ vowel in General British

Cruttenden (2014:122) describes the STRUT vowel as a "centralised and slightly raised CV [a]" and he acknowledges the presence of a back-er quality [ʌ̞̈] in Conspicuous General British speakers, though this quality also appears to be heard more often in GB (I agree! See below). The jaws are said to be separated considerably, and the lips, neutrally open. There is an MRI of a phrase containing STRUT in Gimson's.... companion website here.

Collins and Mees (2012) have defined STRUT as a central, open-mid checked vowel, and admit a certain degree of variation, but especially in terms of fronter qualities. In much the same way, Mott (2011:117) describes STRUT as being "slightly forward of centre, just below half open, unrounded".

The abovementioned authors would then place STRUT somewhere around these areas:
Dark purple: STRUT, according to Mott & Collins and Mees. Light purple: Cruttenden (2014) and the backer quality [ʌ̞̈] he describes as a variant.

Geoff Lindsey has a great post called "STRUT for Dummies" with a myriad audio examples that illustrate his comments on the historical and present variation of STRUT, wavering between [ə] and [ɑ]-like qualities.

Many Argentinian colleagues and I believe that STRUT appears to be moving closer now to an [ɑ] quality, at least for many young speakers. I cannot claim to have the knowledge or "ear" that Lindsey happens to be blessed with, but here's an example of what I believe I hear pretty often:

Compare this young YouTuber Zoella's versions of "love", "until", "one", "somebody", "bump", "tummy", "just", "hundred". Apart from being great examples of intra-speaker variation (I personally don't hear all the versions of the word "love" with the same STRUT quality), there are some other interesting processes going on . (Also, a great taste of the kind of TRAP vowel I hear now, so different from General American versions!).

(BTW, according to Wikipedia, Zoella is from Wiltishire, and currently living in Brighton. What would you say her accent is?)

If we see these variations in acoustic terms (disclaimer: not at all my area of expertise...yet!), we can find in Rogers (2000) there is a table presenting formant values for RP vowels, based on a measurement of adult male speakers in Gimson, 1980. In that measurement, RP /ʌ/ has got the following values:
F1: 760 Hz
F2: 1320 Hz
( Confront with the values that the study by Wells in his 1962 study  had established F1:722, F2: 1236 )

(BTW, in simple terms, F1 inversely represents the articulatory tongue height, so that its higher frequency value represents lower tongue height. F2 represents degrees of backness, with lower values representing back-er vowels).

A study conducted by Hawkings and Midgley (2005) in four different age groups found the following mean formant values for these age groups:

  • F1:630 -F2:1213 for over 65s (higher than the previous studies mentioned, and a bit backer)
  • F1:643 F2:1215 for those speakers between 50-55 (lower than the over 65s, but equally central-back)
  • F1:629 F2:1160 for speakers in the age range 35-40 (higher than those 10 years older, and backer)
  • F1:668 F2:1208 for speakers aged 20-25 (lower than the other groups, but not as back as those speakers a bit older)
So according to this study, in comparison with the previous measurements reported, it would appear to be the case (at least for the speakers surveyed) that younger generations have a lower, and to a small degree, back-er STRUT than older generations).


If you are interested in pursuing this further, there are some interesting studies by
Ferragne and Pellegrini (2010), measuring vowels in 13 British accents.
Sidney Wood (SWPhonetics) analysis of different RP speakers' vowels across time.

***
Riverplate Spanish Vowel /a/

A contrastive analysis between General British and Riverplate Spanish (RS), and also the contributions of Speech Perception theories would lead us to expect that those students with RS as L1 are very likely to interpret English STRUT in the area of Spanish /a/ (not to mention distributional differences!). (BTW, in 2013 I attended a talk by Andrea Leceta at the III Jornadas de Fonética y Fonología, in which a comparative and experimental study on these features had been made, and the results confirmed these expectations. The proceedings have not yet been published, I am afraid.)

García Jurado and Arenas (2005) discuss Riverplate Spanish /a/ as having a wide degree pharyngeal of constriction (following the studies by Fant (1960) that focus the analysis of vowels based on the levels of constriction along the vocal tract) and clear oral opening and lack of lip rounding. They establish a mean F1:800 and F2:1200 values, which appear to match the degree of backness found for current versions of STRUT, though Spanish /a/ is much lower than English /ʌ/. 
Location of Spanish /a/ by Mott (2011)
You can see a cross-section of the articulation of /a/in Spanish and in English in these captures from the University of Iowa's Sounds of Speech app.


 Spanish /a/
(American) English /ʌ/


***
There appears to be an interesting similarity between Spanish /a/ and GB English /ʌ/ that lies mostly in the central part of the tongue employed, and an interesting difference, that is related to the height of the vowel and the level of jaw dropping, much higher than in Spanish, although they are both mid-to-low vowels. And still, it appears to me -and this is a very personal appreciation- that it is not jaw-dropping alone that makes our RS /a/ different from GB  /ʌ/. And my teaching of the sound over the years has also proven to me that jaw-dropping alone does not do the trick.

It may or it may not make sense to teach the exact quality of this sound to RS speakers, and it will depend on whether the focus of the lesson is on accentedness or on intelligibility, but the truth is that for an RS speaker, there needs to be a contrast between the three different qualities making up the contrast STRUT-TRAP-BATH in English, which to RS speakers may be only subsumed into one. 

So the next part of this post, coming up in a new weeks, I will present some "tips and tricks", rooted on some phonesthesic ideas, and also on realia techniques, that may help RS speakers turn their Spanish /a/s into STRUT.


After-post addition:
A reader rightly pointed out that I have not presented audio examples of my own of the difference between both sounds. So this is how I pronounce Spanish /a/ and English /ʌ/, and below you will find two Praat captures of the spectogram and formants of the same versions:


My Spanish /a/

My English /ʌ/

lunes, 20 de abril de 2015

#IATEFL2015 Online Coverage #2: Interview to Luke Meddings

Part of the IATEFL Manchester Conference 2015 online experience included interviews with many delegates and presenters. In a previous post, I reviewed an interview with David Crystal. I would like to briefly comment on the 6-minute conversation a British Council presenter held with Luke Meddings this time. As usual, my own input, in a different colour.

Being 12,000 km away, I did not get to see Meddings' talk, which I was told was hilarious, but I would be happy to hear or read about it online, if anyone out there wants to report on it! (There's a brief reference to his talk and other pron talks in Mark Hancock's blog, BTW)

The interview with Luke Meddings, available here, begins with some points of reflection about the way we feel when we speak another language, the idea of being "frozen up", filled with anxiety, fearful of making mistakes. As the interviewer points out, at times it is this fear or anxiety that may lead us to focus on form, and forget meaning. This is something I generally notice with my advanced students at College: they are so concerned with sounds, or even with their own intonation patterns, that it just sounds as if they are reading "patterns" (as one of my colleagues says), reading a set of marks on the page, totally devoid of meaning. I was just thinking of David Brazil's (1980, 1997) notion of oblique orientation here. And not because my students, necessarily, use many level tones, but because their approach is oblique, even when using fall-rises, or rises! Their concern with form and accuracy is stronger than the expression of meaning and the need to address an audience. Moreover, I generally notice many learners making appropriate choices of tone and nucleus in their reading aloud experiences who fail to get the message across! And this, again, is connected to some features that I sometimes fear we may neglect when teaching pronunciation, and even when teaching speaking skills in general: the contribution of paralinguistic features to the overall meaning, and mood, of a text. 

The approach that Meddings suggests appears to address some of these paralinguistic concerns, as he takes up the idea of "impersonation" through body language and gesture, as well as breath and volume control, as a "key" to pronunciation. From what the interview shows, Meddings appears to have got the "hang" of voice quality and articulatory setting features of different people, like the Queen, or John Lennon, and even makes use of chewing gum to aid his impersonation. I remember students talking about impersonation techniques for English learning used in some English institutes in Buenos Aires. Students were asked to pick a celebrity they liked on their very first day, and they adopted this "second personality" throughout their studies. So one of my students was "Ginger Rogers", and that is what she was called by her teachers during her lessons, for six good years! In spite of the fact that this student did not entirely approve of the method, she said that this approach made her feel safe, as it was "Ginger" who was making mistakes, and not herself. Interesting.

Part of Meddings' premise is that we should learn to "let go", as pronunciation is physical and feedback can get on our skin. Once again, there is an invitation for learners to "find their own way of speaking English their own way". I have been thinking about these issues for quite some time, issues related to the "ownership of your interlanguage accent", to the challenge of "finding your own voice", and I have decided to put some of these ideas into a podcast-like post, coming soon, called "Your Accent, Your Patronus" (Yes, another Harry Potter reference! <3).

All in all, the interview gives us a taste of Luke Meddings' style, and it is always enriching to see other ways of doing pronunciation work in the classroom.

jueves, 16 de abril de 2015

Happy Birthday, Pronunciation Bites!

This month marks the first anniversary of this blog, Pronunciation Bites.

A year ago I came up with this idea and this name, referring to the fact that even though for some teachers pronunciation appears to "bite" -and so decide to stay away from it-, it does and should not!I wanted to prove the opposite by offering teachers the possibility of "grabbing a bite" from the myriad resources I have collected, and a few thoughts inspired in my teaching practices and misadventures.

C3 Estudio designed the logo for me, based on an original PacMan-eating-phonetics-symbols idea, and off I went into the online jungle.
My own version, made with the Windows programme Paint.
C3 Estudio's design after 7 different versions! Looking pretty!


A year later, Pronunciation Bites is a whole virtual experience, with this blog, a Facebook page and a Twitter account where more daily findings and remarks are posted, a ScoopIt! collection of lots of articles, ideas, videos, tutorials I have found on the Web organized through tags, and a small Pinterest collection of clippings that teachers may find of use.

My readers, as far as I can see, are based all over the world, and they are teachers, speech therapists, phonetics enthusiasts, publishers, and some of my own students, with ages ranging from 19 to 85. And the greatest thing is that not everyone agrees with everything I say, and that is, by far, the most enriching aspect of what the Internet allows us to do: debate.

I have had, and still have, many misgivings during the process. In spite of the fact that I have been a teacher for only 15 years, and a Phonetics lecturer for almost 9 years -not a long time in comparison with other bloggers and experts on the Internetsphere-, I feel I have a lot to say about Phonetics and pronunciation teaching and I believe that I know quite a lot about it, more than I have been able to write. I believe that putting those thoughts "out there" is truly worth it, but I am aware that as I write, each word and thought is squeezed through a number of filters, because I still fear what people may think or say. And it is this fear that probably leads me to keep writing. I know this is part of the learning process that I will need to make as an inexperienced and confidence-seeking blogger and teacher.

Another thing I struggle with is, in fact, a product of this competitive academic environment we live and work in. I really admire those people who so freely share their own handouts and games on the web, like Annie McDonald and Mark Hancock, and many other brave teachers out there (see a list on the Facebook page: Free and Fair ELT). I have received well-meaning warnings of the kind "someone will steal that idea from you", "I would not voice that thought if I were you", "you are giving away information that can make you vulnerable", "what will your students say?". Much as I keep these thoughts in the back of my mind, I have become what I have become because of people who have shared their knowledge, expertise, criticism, and bookshelves with me. If these tutors and mentors had simply kept their worlds of knowledge to themselves, I would not have learned so much. So I will try to pay my debt to them by sharing. As much as I can. All the time.

They say that "a candle loses nothing by lighting another candle" and I firmly believe that Pronunciation Bites is a space of light for me, a place that has allowed me to have a voice, an outlet, and an opportunity to share my passion for phonetics & phonology in general, and pronunciation teaching, which is what I do for a living (and not just for money, mind you, this really keeps me and my enthusiasm alive!).

This year, apart from more introspection/reflections, book reviews, webinar/conference reports, I intend to introduce teaching ideas and materials designed by me. I would also like to allow myself to show some of my knowledge of phonetics, and especially, of prosody and pragmatics. And I will probably come up  with some other initiative, as by now you should know I can't stay still!

A HUGE Thank You to all readers and followers out there, and I hope my Pronunciation Bites space provides you with inspiration, ideas, materials and courage to make pronunciation part of your daily lessons. Thanks a million for your support!

lunes, 13 de abril de 2015

#IATEFL2015 online coverage #1: Interview with David Crystal

As a Manchester, IATEFL 2015 registered blogger, I have to admit I have not had the time to catch up the way I would have liked to, but here I am, with my first report.

This time, I'll be talking about an interview with David Crystal (available here), which of course, was the obvious choice for me to start!

As usual, a bit of a report of what was said, and my own input, in a different colour.

***

The Crystals have been pretty active in this 450th celebration of Shakespeare's wonders, and they have been busy publishing materials for all our enjoyment. The illustrated Shakespearian dictionary is mentioned by David, with a few interesting tips and tricks regarding our approach to Shakespeare in the classroom:

  • Shakespearean language has to be learned in context, and we need to have the pictures in our head of what these words represent in order to make sense of the images Shakespeare so very skillfully presents!
  • Before approaching the play on paper with your students, see it on stage or watch a DVD! I looooved this bit of advice. Watching "a book" on DVD/YouTube/stage should not be a "sin" or a form of "cheating", it is yet another interpretation of the book in print through the eyes of the semiotic systems of image, sound, motion, and I agree entirely that this is a valid way of going about it!
  • Act a bit of Shakespeare in the classroom. Nothing more exciting, methinks!

Now off to my personal favourite bit: Original Pronunciation. I've written about this in my review post of the latest Crystals' book here, but I would like to write down some of the points David raises in this interview.

David reminds us that the powerful resource of rhyme in Shakespeare's sonnets (because if I remember correctly blank verse does not rhyme except in the last verses of each scene?! Do I remember my Shakespeare?!) does "not appear to work in Modern English". We all remember the lovely Sonnet 116, and the supposed rhyming pair "loved"-"proved" [lʌvd - pru:vd], which in OP would be something like [lɤvd - prɤvd]. You can hear more about it here:


Crystal invites us to experience Original Pronunciation (OP) here:
http://originalpronunciation.com/

The last part of the interview leads us back to the "You Say Potato" book. Apart from retelling some bits from the book, David mentions the fact that the accent issue is complex, and that in order to faithfully represent the idea of how accents change, there had to be more than one person in the book, a "young person, and a slightly less young person". He mentions the fact that there will be an audiobook version later in the year (looking forward to it!)


There is an interesting discussion in the interview regarding the notion of accents. As we have heard countless times, accents are "all over the English speaking world" and they are "mixed". We are no longer speaking about RP as the norm, but as a "mixed or modified RP", what other authors called General British, which Crystal defines as "educated, understandable". This is a complex issue as well, in my opinion. Clearly, if you read the news, what the media sees as RP is the "Queen's English" or the "Public School English" which Cruttenden (2008) called "Refined RP" and is now termed "Conspicuous General British". I think this RP they may be talking about, spoken by 2% of the population, is not necessarily what we may call "General British" and of course, "Regional General British", which I associate more with universities and the media.  So when we say "RP", what are we really talking about? I would also question the use of the term "understandable", as my students would claim that it is General American that sounds "intelligible" to them, and not really British varieties, but it may be a problem of exposure. Worth another post!

Crystal then addresses learners of English by urging them to embrace the idea of keeping traces of their native language in the accent of English, except for "spies, who are the only ones who need to be anonymous" (LOL!). He sees English as a "garden of flowers", with each individual accent making a different variety and bringing colour to it (<3). David tells teachers that the priority should be students' clarity, and an approach to flexibility, that is, not focussing on teaching every single feature of an accent to students. He mentions, for example, the features of glottalisation (as in [hɒt -hɒʔ] and GOOSE-fronting (as in [ku:l - kʉ:l]), clear examples of the changes to General British, that ought to be accepted in the English classroom. Exposure to different accents as early as possible is key. Crystal does make a point as well of "knowing how to do it", that is, having the necessary tools to teach pronunciation of the accent(s) of choice. (Worth another post! #2)

As an answer to a question on the importance of stress and connected speech over the segmentals, David believes there is more an issue of complementarity. David also mentions the fact that if we look at the different Englishes around the world, 3/4 of the speakers actually employ syllable-timed versions of their accent, which is why, in his opinion, stress-timing as a teaching priority is actually outdated. The challenges to the "stress-timing" hypothesis have been going round since the early 1980s, including some papers by Peter Roach and Cauldwell, among many others. Very very interesting topic, by the way.

To conclude, Crystal presents some pieces of advice for teachers to "keep up with the times" by "listening, listening, listening" to English, to young speakers of English in the media, especially social media, in the understanding that the young speakers of the language are the ones pushing the language forward, the future parents of the future generations. He reminds us that we should not underestimate the power of Internet, as these generations take "screens as central, books as marginal".

All in all, a short, yet enjoyable interview, with that lovely accent of Crystals' (IMO) and his smooth, "surfable" intonation patterns (really worth teaching!), but first and foremost, with a very engaging discussion of hot topics which may at times be a bit "thorny" for teachers.

I expect to be able to report more on the online coverage of IATEFL 2015 soon!


jueves, 26 de febrero de 2015

A PS to my latest post: Pronunciation goals and models - Part 2: What the experts say

Pronunciation goals and models - Part 2 - What the experts say


In one of my latest posts, I discussed a number of key questions we should ask ourselves when deciding what accent to teach, what we would like our students to achieve, how we would like to go about it, among other issues for pronunciation planning.


In this post, I intend to briefly review what the "big names" in pronunciation teaching have said. As usual, some disclaimers acting as a "foreword":

  • I will be mostly referring to "pronunciation goals", but I will also be including issues connected to "pronunciation models" as well.
  • In spite of the fact that much of the current bibliography does not favour the terms "native" or "non-native", I will employ them in this post, for the sake of clarity.
  • I have organised the information chronologically, from the latest editions of the materials reported, to the earliest.
  • This is by far NOT all the bibliography on the topic, but I have decided to begin by referring to those materials which are very popular in the ELT world.
  • I will not pass (explicit) judgement on the views presented by the authors. As I claim in my previous post, the teaching contexts that exist for English lessons are so vast, that a single answer, a single target, cannot be set as "universal", so I think that all these authors have a great contribution to make to the debate.


Brown establishes three "I"s in the setting up of pronunciation targets: Intelligibility, Image and Identity.

Intelligibility is seen as a "scalar continuum" including notions of both "intra-" and "inter" national range. Brown reviews notions of "restricted intelligibility" (Cruttenden, 2001) and "comfortable intelligibility" (Abercrombie, 1956). The author believes that the difference between these ideas lies on the original authors' standpoints: whereas Cruttenden on Gimson's behalf discusses the notion of intelligiblity from a native speaker's perspective, Jenkins (seen as represented by Abercrombie's view) responds to communication in English among non-native speakers. Brown also introduces another of Gimson's points: high acceptability. This is defined as "a level of attainment in production, which for the native listener, is as readily intelligible as that of a native RP speaker and which is not immediately recognizable as foreign" (Cruttenden 1995: 276). Brown comments on the fact that acceptability is generally put together with intelligibility, and poses the question "intelligible and acceptable to whom?".

The second "I" is "image", and it has got to do with the way non-native speakers of English want to be perceived by others (a sort of "face giving" idea, I guess).

The third "I" refers to "identity", and it covers a very important aspect regarding accents, which other authors refer to "ego permeability": how much of the foreign accent you want to attain in order to keep your "identity", your idea of self. 
Quoting Tabouret-Keller (1985), Brown acknowledges that linguistic behaviour has a role to play in both personal identity and social roles, which is why all these three "I"s are in fact, in tension. This continuum of targets has been presented by Brown, thus:


Cruttenden first acknowledges that even though RP (GB) used to be the native-speaker accent taken as the norm in ELT, nowadays it competes with other native accents, such as General American (GA) or Australian English. The author admits that many English language users have "no realistic possibility or necessity to acquire a standard native-like accent" (p.327). Those learners using English as a Lingua Franca or as an L2 may want to acquire an "Amalgam English" accent, "based on an amalgam of native speaker Englishes, together with some local features arising from a local L1". Likewise, they may want to use what is known as "International English". Cruttenden admits the distinction between these Englishes would not be easy to make, and associates the former variety to a "hybrid between American and British varieties, and possibly varieties from the southern hemisphere and the Caribbean as well....and transfer from the local L1". International English includes features of Amalgam English plus tolerating "a much wider adaptation to features common in other languages".


Derwing, T and M. Munro (2014) "Accent and intelligibility: cracking the conundrum". In Speak Out, Issue 50 (pp. 12-16).

These authors present a number of studies aimed at discussing perceptions of non-native accents of English. They discuss the notion of intelligibility as "the degree of a listener’s actual comprehension of an utterance", and cross-compare it with perceptions of comprehensibility "listeners’ perceptions of how easy or difficult it is to understand speech" and accentedness, the "the result of differences in speech patterns compared to a local variety". They have found that many samples of speech rating high in accentedness were also highly intellibigle, thus, both features are seen to be independent. Comprehensibility, however, is more closely connected to intelligibility, though still retaining some independence as well. The authors summarise the role of these three variables, thus: "accent is about difference; comprehensibility concerns the listener’s effort; and intelligibility is the end result: how much the listener actually understands (Munro, 2008)". 
Derwing and Munro advocate explicit pronunciation instruction but with the right focus on intelligibility and comprehensibility, as at times focusing on reducing accentedness may lead to a neglect of these other factors, more essential for communication, or threaten a learner's identity, the authors claim. Plus, the authors believe that many features of accent are non-volitional, and thus, "outside the speaker's control". Therefore, they believe that "if one is intelligible and comprehensible, one’s expression of identity will be more effective", so in other words, training on these first features will enhance the possibilities for self-expression. Derwing and Munro also point out that communication is two-way, and listeners also have an important bearing on the whole process, so their willingness to contribute to the process and leave aside prejudice is essential. 
More research is needed, the authors conclude, to establish the weight of the different variables in different contexts of communication and instruction.


This author invites us to ask ourselves a few questions in order to reflect about our "gut feelings" regarding foreign accents:
  • Imagine you are talking in your first language to a NNS. The person doesn't speak your language ver well and is difficult to understand. What do you do?
  • What do you say when the NNS apologises for their poor accent?
  • How do you feel when a NNS pronounces your name wrong?
  • How do you feel when you meet a NNS who speaks you language with a near perfect accent?
Rogerson-Revell acknowledges the complexity of the targets issue, and reminds the reader that "pronunciation can be a more sensitive area of language learning than other areas, such as grammar and vocabulary, in that it involves modification of accent which can raise issues of attitude and identity". Rogerson refers to the view of Kenworthy 1987 and Roach 2000 regarding the "need for teachers to acquire a high level of proficiency in target language pronunciation", while "willing to consider ELF (English as a Lingua Franca) goals for students". These conflicting interests add to the goal of intelligiblity, the ideas of performance and proficiency as well.

Walker vastly reviews bibliography and statistics that prove that English is a global language, and that non-native speakers of English are by far more likely to communicate with other non-native speakers of English than with speakers of English as an L1. This author believes that "the primary goal of teaching pronunciation must now be to make learners intelligible to the greatest number of people possible, and not just to the native speakers of the language". Added to this, Walker remarks that "many users from Expanding Circle may want to retain their local accent as a mark of their identity". (BTW, the "Expanding Circle" refers to one of the layers of Krachu's 1985 model describing the profiles of English users, consisting of "those countries where English is neither a first language, a second language, nor an official language" (Walker, 2010:4)).
As regards the ideas of intelligibility and identity, Walker refers to Kirkpatrick's (2007) continuum of functions, going from "mutual intelligibility" towards "identity". Apart from these two goals, Walker includes Dalton and Seildhofer's (1994) reference to the notion of "teachability". These three goals need to be considered in an ELF approach, as the "Lingua Franca Core", the set of features of pronunciation set up as essential to ensure successful communication among non-native speakers of English also ensures teachability (as they can be achieved through classroom teacing) and identity, as learners can retain features of their local accents, Walker states.

More on ELF and the LFC:
Laura Patsko and Katy Simpson's blog: https://elfpron.wordpress.com/


The authors review a number of groups of English learners that require a high level of intelligibility: "foreign language assistants; foreign born technical, business and professional employees; international business people and diplomats; refugees in resettlement and vocational training programmes; teachers of English as a foreign language who are non-native speakers of the language (who expect to serve as the major model and source of input in English for their students); people in non-English-speaking countries working as tour-guides, hotel staff, customs agents."

However, they acknowledge that in spite of this need for high intelligibility, a native-like pronunciation can be an unrealistic goal. The authors believe that learners should be able to "surpass the threshold level so that their pronunciation will not detract from their ability to communicate" (p.8)

Donna Brinton's numerous presentation slides: http://es.slideshare.net/brinton


In the introduction to the really valuable set of activities in this book, Hewings presents a number of questions. One of those questions is related to the accent that students should be taught, which depends on:
  • the contexts that the students will be using English at
  • the low or high status of certain varieties in the teaching context
  • the inclination students may have to speak a certain variety
  • the teaching materials available
  • the accent the teacher her/himself happens to have.
Hewings presents a distinction between a model as a "target" (a pronunciation standard to which students or the teacher select or aspire to), and one as a "point of reference" (a model presented as an acceptable guide, as long as it does not interfere with communication)

The second question relates to "how good" our students' pronunciation should get. This is a key question in the bibliography, as the "native speaker" is no longer the rule when it comes to English for communication, and Hewings also claims that some students may not even find this "desirable", or it may not be really "achievable". This author believes that an "appropriate and reasonable goal is to achieve an English pronunciation which is usually understandable in international communication, but retains unobtrusive features of a non-English accent". 
However, Hewings alerts the readers to the fact that there are a few factors that may influence our choice of features and targets. The fact that younger learners can easily "pick up" foreign accent features, for example, may lead us to aim for a more "native like" variety if we wished. Another feature Hewings considers is the "tolerance or experience" of the interlocutors our learners will be interacting with.


Kelly defines pronunciation model as "the pronunciation characteristics of the language a teacher presents to learners in the classroom". This author makes a point of the fact that teachers need to be aware of different variants and accents of English, and of the present role of RP as well. He concludes that teachers can "work on issues of production and reception independently, enabling students to understand a wide range of varieties, while allowing them to choose their own target model so long as it is widely comprehensible". As a final piece of advice, Kelly suggests that teachers should "teach what they know and use, and be as informed as they can be about other varieties".

Gerald Kelly's Twitter account: https://twitter.com/GeraldKellywork


Pennington adopts a "variationist approach" to teaching phonology, which implies that "learner's individual circumstances should dictate the targets of language learning". The author proposes exposing learners to "multiple models of English phonology" and then involve them actively in "deciding what they will learn and in developing their own learning process" to enhance "collection, not correction" (Esling, 1987).

Pennington believes that the most pressing goal is intelligibility, and that this dictates the need for feedback in the lesson, no matter how much explicit instruction on pronunciation may be given. As the learner advances from beginning to intermediate levels, the author presents the need to consider other goals, such as fluency, and also accuracy in terms of "audience-determined norms". For some speakers, Pennington claims, functioning in the target culture also entails "mastering those aspects of pronunciation that define a person's attitude, mood, orientation to the audience and the topic, and other basic characteristics of the speaker's personal, social and cultural orientation" (p.221). The author goes further to say that these speakers may need to focus on "casual and expressive ability in phonology" to avoid being assessed as "stand-offish" or "unfriendly".

Like previous authors, Pennington considers that the decisions on goals begin from intelligibility and can then be further defined in terms of "what is feasible under the constraints of the course (...) and in the context of other decisions about what to teach and on what schedule" (p.222)


Kenworthy recognises that native-like pronunciation may be an inadequate goal, given that many learners have "practical" aims for learning English. Those who strive for native-like pronunciation may do so because of an occupation-related priority, including teachers, who may want to not only approximate this goal, but who should also become exposed to as many varieties of English as possible.

A realistic goal for the general language learner according to Kenworthy is to become "comfortably intelligible". The use of the word "comfortable" refers to the interlocutor's "tolerance" in trying to understand the message put forward by the non-native speaker. Intelligibility is defined by the author as "being understood by a listener at a given time in a given situation" (p.13), and it is measured in terms of how many words can be understood. Kenworthy believes that this aim may be "close enough" to a native-like goal in terms of contrasts that would enable a native-listener "match the sound heard with the sound (or feature) a native speaker would use without too much difficulty", thus intelligibility is dependent on "counts of sameness". Intelligibility is closely related to successful communication in terms of "efficiency, effectiveness and speaker's intentions".

***
This humble selection of readings has presented some of the most important points in the "pronunciation goals and models" debate. The key issues raised include:
  • intelligibility: comfortable? restricted? international? intranational?
  • identity and ego-permeability, image and accentedness
  • acceptability
  • comprehensibility
  • native vs non-native interlocutors
  • native-like accent norms
  • model as "target" or "point of reference"
  • efficiency, effectiveness and speaker intentions
  • occupational-related goals
  • perception vs production
  • teachability and attainability
Want to read more?
Have you read other sources? Share them with us in the "Comments" box below!